Marina Lyubimova
The difference is simple: 3.8 Live prioritizes latency and cost, while Extended Thinking adds multi-step reasoning and background tool execution. Both are available through Google AI Studio and the Gemini API.
Technical specifications
| Gemini 3.8 Live | 3.8 Live Extended Thinking | |
| Input | Text, image, audio, video | Text, image, audio, video |
| Output | Text, audio | Text, audio |
| Input limit | 131K tokens | 131K tokens |
| Output limit | 65K tokens | 65K tokens |
| Reasoning | Interleaved | Background, multi-step |
| Thinking levels | — | Low/Medium/High |
| Function calling | Blocking + non-blocking | Non-blocking |
| Visual grounding | Yes | Yes |
| Languages | 97+ | 97+ |
| Target | High-volume voice apps | Complex agents |
Audio pricing starts at approximately $0.005/min for input and $0.018/min for output, equivalent to about $0.30 and $1.08 per hour, respectively.
Gemini 3.8 Live vs. Gemini 3.1 Flash Live
Gemini 3.8 Live replaces the previous gemini-3.1-flash-live-preview. The standard model remains focused on real-time conversation, but 3.8 expands the architecture around multimodal grounding and asynchronous tools.
The bigger change is Extended Thinking. Unlike 3.1 Flash Live, it can reason, call tools and continue speaking without waiting for the entire task to finish.
3.8 Live Extended Thinking reasons and speaks simultaneously. — Google
This changes how completion is handled.
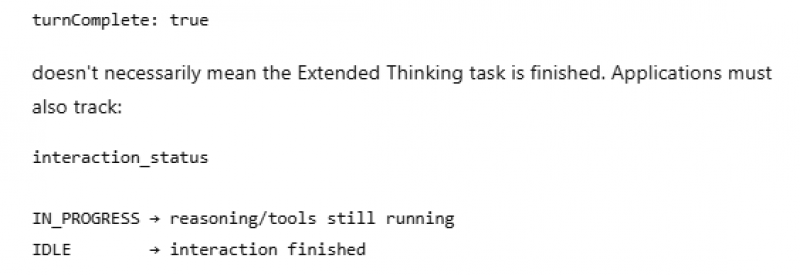
Extended Thinking requires non-blocking function calls and supports configurable reasoning levels:
- low
- medium
- high
Asynchronous agents
A voice agent can now respond immediately while continuing work in the background.
For example:
User request → Immediate voice response → Background reasoning → API / tool calls → Additional voice response
This is useful for workflows involving bookings, support systems, database queries or multiple external APIs. Both models also support visual input, allowing an agent to combine live audio with camera or image context.
Benchmarks
Google reports the following results for Gemini 3.8 Live Extended Thinking:
| Benchmark | Result |
| Speech-to-Speech Quality Index | 82.6 |
| Big Bench Audio | 97.7% |
| τ-Voice | 68.6% |
| Sierra τ-Voice Banking | 35.1% |
These are vendor-reported benchmark results rather than measurements of application latency or production reliability.
For developers
Use Gemini 3.8 Live when latency, scale and API cost matter most: customer support, voice assistants, language apps and real-time interfaces. Use Extended Thinking when one request can require several reasoning or tool steps.
The main migration difference is therefore architectural:
- Gemini 3.1 Flash Live → real-time dialogue
- Gemini 3.8 Live → faster/scalable real-time dialogue + multimodal tools
- Gemini 3.8 Live Extended Thinking → dialogue + persistent reasoning + asynchronous agent workflows
 Marina Lyubimova